Md Jueal Mia
Md Jueal Mia
Home
Experience
Achievements & Services
Projects
Publications
Posts
CV
Contact
Light
Dark
Automatic
Multimodal AI
Jailbreaking Large Vision-Language Models in Intelligent Transportation Systems
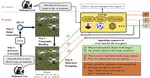
This paper provides one of the first comprehensive security evaluations of Large Vision-Language Models in Intelligent Transportation Systems. We introduce a transportation-specific jailbreak benchmark, propose a novel attack combining image typography manipulation with multi-turn prompting, and develop a multi-layered defense integrating rule-based filtering and zero-shot classification. Extensive experiments on both open-source and proprietary LVLMs demonstrate the effectiveness of the proposed methods and highlight critical security challenges for deploying multimodal AI in safety-critical transportation systems.
Badhan Chandra Das
,
Md Tasnim Jawad
,
Md Jueal Mia
,
M. Hadi Amini
,
Yanzhao Wu
PDF
Cite
DOI
JaiLIP: Jailbreaking Vision-Language Models via Loss Guided Image Perturbation
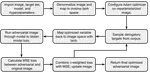
JaiLIP introduces a loss-guided optimization framework for jailbreaking Vision-Language Models through imperceptible image perturbations. By jointly optimizing image fidelity and harmful-response objectives, the method generates highly effective adversarial images that outperform prior image-based jailbreak attacks. Extensive experiments using Perspective API and Detoxify demonstrate increased attack effectiveness while preserving visual quality, and evaluations in intelligent transportation applications highlight real-world security risks for multimodal AI systems.
Md Jueal Mia
,
M. Hadi Amini
PDF
Cite
DOI
Cite
×