QuanCrypt-FL: Quantized Homomorphic Encryption with Pruning for Secure Federated Learning
 QuanCrypt-FL: Quantized Homomorphic Encryption with Pruning for Secure Federated Learning
Abstract
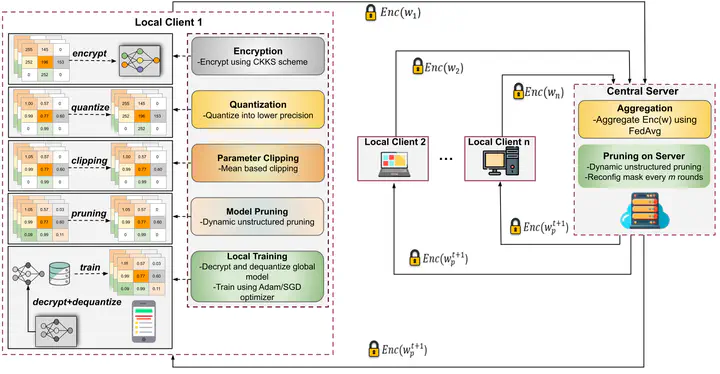
Federated learning has emerged as a leading approach for decentralized machine learning, enabling multiple clients to collaboratively train a shared model without exchanging private data. While federated learning enhances data privacy, it remains vulnerable to inference attacks, such as gradient inversion and membership inference, during both the training and inference phases. We propose QuanCrypt-FL, a communication-efficient federated learning framework that integrates fully homomorphic encryption (FHE), low-bit quantization, dynamic pruning, and a novel mean-based clipping strategy to provide strong privacy protection while substantially reducing computational overhead. By combining these techniques, QuanCrypt-FL defends against inference attacks, minimizes encryption and communication costs, and preserves model accuracy. Extensive experiments on MNIST, HAM10000, CIFAR-10, and CIFAR-100 demonstrate that QuanCrypt-FL consistently matches the accuracy of Vanilla-FL while outperforming existing privacy-preserving approaches, achieving up to 9× faster encryption, 16× faster decryption, 3× faster training, and 1.5× faster inference.
Md Jueal Mia
Graduate Research Assistant
My research interests include Trustworthy AI, AI Security, Foundation Models, Large Language Models, Vision-Language Models, Agentic AI, Federated Learning, Privacy-Preserving Machine Learning, and Adversarial Machine Learning.