 JaiLIP: Jailbreaking Vision-Language Models via Loss Guided Image Perturbation
Abstract
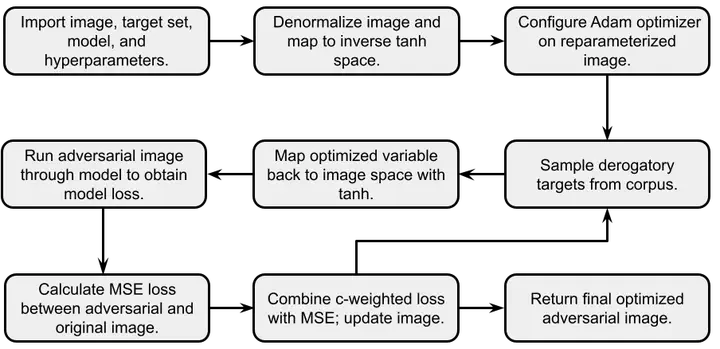
Vision-Language Models (VLMs) have demonstrated remarkable capabilities in multimodal reasoning and generation. However, their widespread adoption has also introduced significant safety and security concerns, particularly regarding jailbreak attacks that bypass alignment mechanisms. We propose JaiLIP (Jailbreaking with Loss-guided Image Perturbation), a novel image-space jailbreak attack that optimizes a joint objective combining the mean squared error (MSE) between clean and adversarial images with the model’s harmful-output loss. This optimization produces highly effective yet visually imperceptible adversarial examples capable of inducing unsafe model behavior. We evaluate JaiLIP using Perspective API and Detoxify toxicity metrics across multiple Vision-Language Models. Experimental results show that JaiLIP consistently outperforms existing image-based jailbreak attacks while maintaining minimal visual distortion. Furthermore, we demonstrate the practicality of the attack in intelligent transportation scenarios, highlighting security vulnerabilities of multimodal AI systems and motivating the need for stronger defense mechanisms.
Md Jueal Mia
Graduate Research Assistant
My research interests include Trustworthy AI, AI Security, Foundation Models, Large Language Models, Vision-Language Models, Agentic AI, Federated Learning, Privacy-Preserving Machine Learning, and Adversarial Machine Learning.